E19 · Candidate release
Synthetic practice, not company performance.
One decision
Does a better average justify deployment?
Run the exact query
SELECT c.slice,r.candidate,COUNT(*) cases,SUM(r.task_pass) passes,AVG(r.task_pass*1.0) pass_rate,SUM(r.critical_error) critical_errors,AVG(r.cost_usd) mean_cost_usd,AVG(r.latency_seconds) mean_latency_seconds FROM sim_eval_results r JOIN sim_eval_cases c USING(case_id) WHERE c.split='heldout' GROUP BY c.slice,r.candidate;
Download SQL · Result CSV · Metabase saved question
Chart and reading
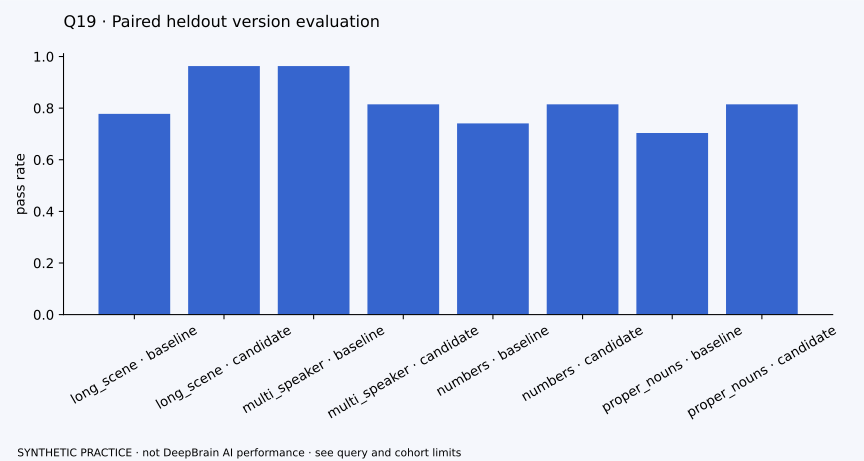
Pair heldout source cases and inspect critical errors, latency and cost by slice.
Challenge your recommendation
Does a critical slice get worse?
Guardrails: Fictional paired cases, not actual model output; no real release evidence.
Next evidence: Rights-cleared real media, independent bilingual labels and source-isolated split.
PRD sections: 12, 13, 17. Open proposed PRD
Your spoken decision
State one takeaway, one caveat and one action in 30 seconds. Then stop.
Connect this finding
What this chart helps decide · Follow the connected decision · Canonical metric definitions
Optional model answer — try your own first
E19 · Candidate release
Decision: Does a better average justify deployment?
Readout: Pair heldout source cases and inspect critical errors, latency and cost by slice.
Actual query output (synthetic), first rows:
| slice | candidate | cases | passes | pass_rate | critical_errors | mean_cost_usd | mean_latency_seconds |
|---|---|---|---|---|---|---|---|
| long_scene | baseline | 27 | 21 | 0.7777777777777778 | 0 | 0.4110370370370371 | 429.3333333333333 |
| long_scene | candidate | 27 | 26 | 0.9629629629629629 | 1 | 0.42362962962962963 | 382.22222222222223 |
| multi_speaker | baseline | 27 | 26 | 0.9629629629629629 | 0 | 0.2922592592592593 | 320.8888888888889 |
Model spoken answer: I would hold a candidate with unresolved critical failures even if its average score improves.
Caveat/counterargument: Does a critical slice get worse? Fictional paired cases, not actual model output; no real release evidence.
Next evidence: Rights-cleared real media, independent bilingual labels and source-isolated split.
Deliberately left out: Synthetic pass rates as proof of real model superiority.