E07 · Latency without arithmetic errors
Synthetic practice, not company performance.
One decision
Should the team reduce queue time or reviewer wait?
Run the exact query
WITH b AS (SELECT * FROM v_task WHERE ('all'='all' OR persona='all') AND ('all'='all' OR workflow='all') AND ('all'='all' OR substr(signup_at,1,7)='all') AND date(created_at)>='2026-05-01' AND date(created_at)<'2026-10-01') , ranked AS(SELECT workflow,ready_seconds,ROW_NUMBER() OVER(PARTITION BY workflow ORDER BY ready_seconds) rn,COUNT(*) OVER(PARTITION BY workflow) n FROM b WHERE ready_at IS NOT NULL) SELECT workflow,MAX(n) completed_tasks,MIN(CASE WHEN rn>=0.5*n THEN ready_seconds END) p50_seconds,MIN(CASE WHEN rn>=0.95*n THEN ready_seconds END) p95_seconds FROM ranked GROUP BY workflow;
Download SQL · Result CSV · Metabase saved question
Chart and reading
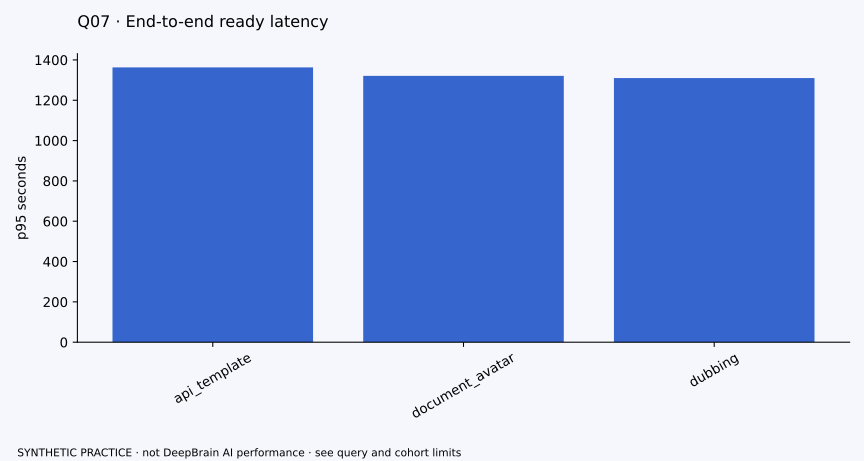
Compare root ready latency with completion and Q23 human wait.
Challenge your recommendation
Are incomplete slow tasks excluded?
Guardrails: Creation to visible-ready includes wait/retry. Completer-only; inspect non-completion in Q02. Not sum of component p95.
Next evidence: Trace spans, timeouts and status UI observations across comparable workloads.
PRD sections: 11, 14. Open proposed PRD
Your spoken decision
State one takeaway, one caveat and one action in 30 seconds. Then stop.
Connect this finding
What this chart helps decide · Follow the connected decision · Canonical metric definitions
Optional model answer — try your own first
E07 · Latency without arithmetic errors
Decision: Should the team reduce queue time or reviewer wait?
Readout: Compare root ready latency with completion and Q23 human wait.
Actual query output (synthetic), first rows:
| workflow | completed_tasks | p50_seconds | p95_seconds |
|---|---|---|---|
| api_template | 329 | 388.0000278353691 | 1363.0000099539757 |
| document_avatar | 307 | 419.0000206232071 | 1320.9999963641167 |
| dubbing | 241 | 378.0000016093254 | 1310.0000157952309 |
Model spoken answer: I would measure whole-task latency and completion first; component p95 values cannot simply be added.
Caveat/counterargument: Are incomplete slow tasks excluded? Creation to visible-ready includes wait/retry. Completer-only; inspect non-completion in Q02. Not sum of component p95.
Next evidence: Trace spans, timeouts and status UI observations across comparable workloads.
Deliberately left out: A promised service-level target without real baseline or load evidence.